Get the data
Filter with the CSV tables first, then download only the ~27 GiB chunk archives you need. Each song directory holds stems, a linear-sum mix, and paired MIDI.
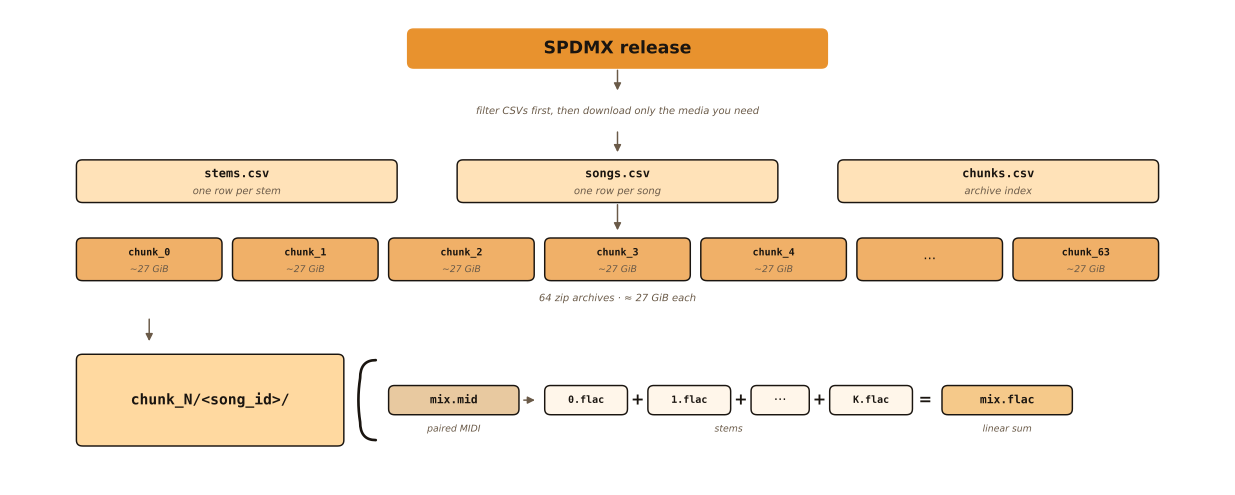
chunk_N archives,
then open chunk_N/<song_id>/ for stems, mix, and paired MIDI.
Download recipe
- Get
stems.csv,songs.csv,chunks.csv. - Filter songs (e.g.
subset:bdgporn_tracks >= 2) then restrict stems. - Read distinct
chunkids and fetch thosechunk_N.zipfiles. - Unzip beside the CSVs so
./chunk_N/<song_id>/…resolves.
Per-song contents
- track — contiguous index after dropping empty PDMX tracks (
{track}.flac). - program / is_drum — General MIDI identity after name-based correction.
- mix.flac — raw linear sum of stems (mono).
- mix.mid — paired MIDI aligned to the stems.
Songs per chunk
Archives are sized for ~27 GiB downloads, not equal song counts.
Dataset at a glance
Interactive plots mirroring the paper figures. Song-hours count mix duration once per song.
Song hours by stems per song
SPDMX vs Slakh2100 (log y). For each stem count, y is total mix hours of those songs.
Scale vs peers
On mix duration, SPDMX is about an order of magnitude beyond Slakh2100.
Stems per GM program
Top programs by stem count after GM register correction.
Hours per GM program
Same ranking; hours are non-silent (RMS-active) stem time when available.
GM classes (songs)
Piano covers most of the catalog; ensemble and orchestral families form a smaller second tier.